
Implementing tiered tables#
Tiered tables provide a unified storage architecture by combining Postgres Distributed (PGD) AutoPartition with Postgres Analytics Accelerator (PGAA) to create an automated data lifecycle. When a standard heap table is converted to a tiered structure, the system manages the transition of data from transactional to analytical storage without manual intervention, providing zero-touch data lifecycle management that optimizes storage costs.
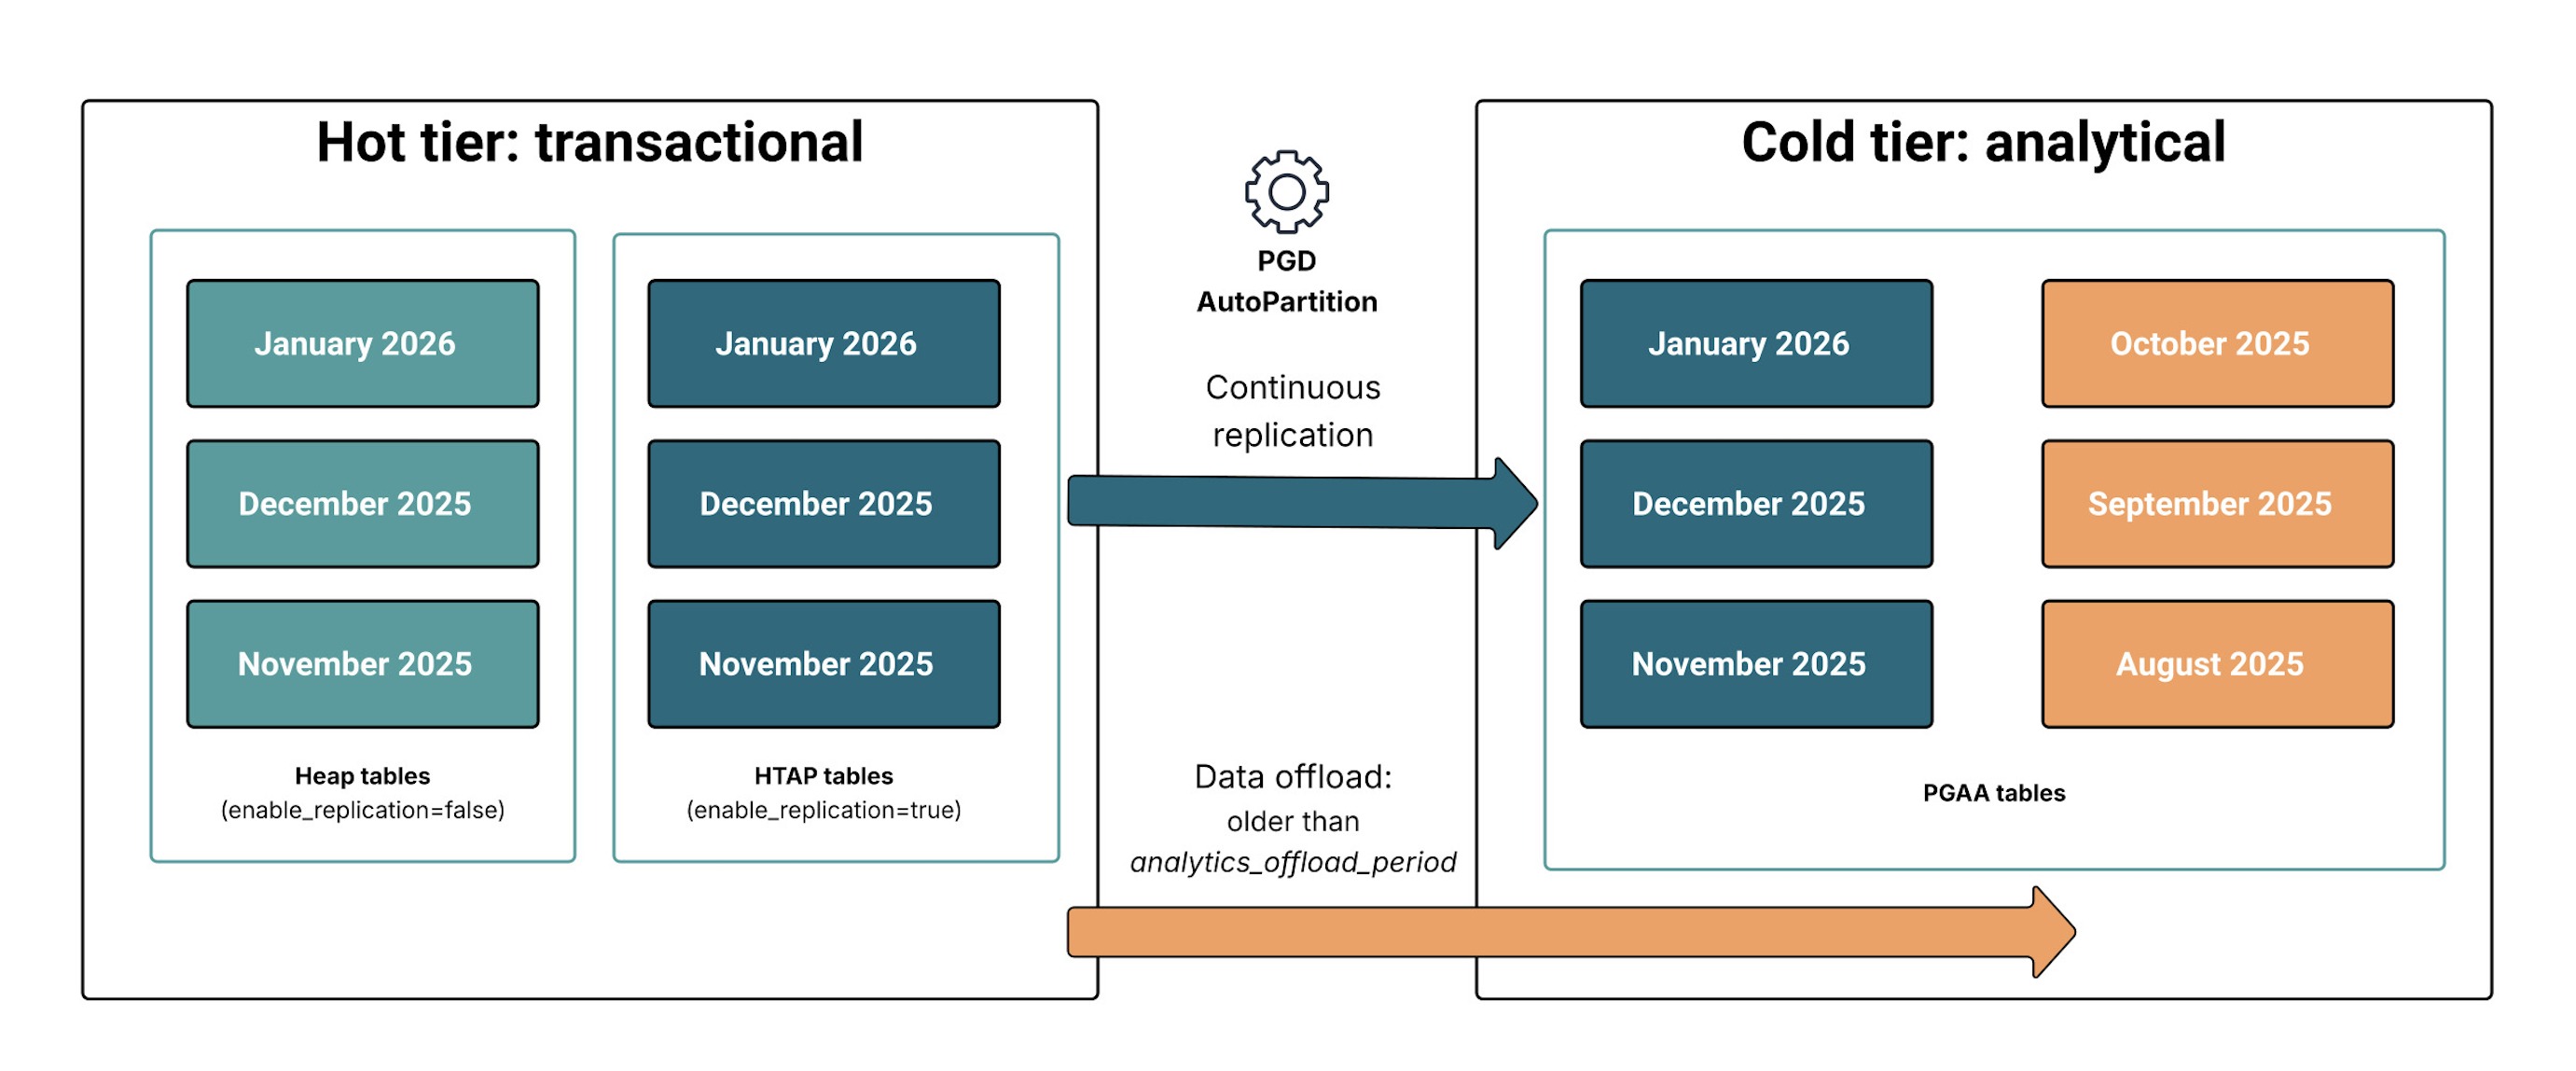
tiered_tables#
In this architecture, queries span both hot and cold data tiers seamlessly, providing a single point of access for the entire dataset regardless of its physical location. Recent data remains in local heap partitions for high-performance transactional processing, while older cold partitions are offloaded to object storage transparently once they cross a defined age threshold.
By calling pgaa.convert_to_tiered_table() , a standard heap table is
transformed into a hybrid partitioned structure:
Hot tier: Recent data stays in local heap partitions, or Hybrid Analytics and Transactional Processing (HTAP) tables if replication is enabled. For HTAP, PGAA uses Iceberg Merge-on-Read (MoR) to capture updates and deletes as lightweight “delete files.” This keeps the cloud tier synchronized without the overhead of rewriting large data blocks.
Cold tier: Once partitions cross a the age threshold defined by
analytics_offload_period, they are automatically converted to PGAA tables in the data lake. Local storage is reclaimed, but the data remains transparently queryable through the same table interface.
Process overview#
To convert a heap table into a tiered table, follow these steps:
Getting started by choosing either a storage location or a catalog service.
Use the
pgaa.convert_to_tiered_table()function to Converting a heap table to a tiered table .Monitoring tiered tables the automated offloading.
Modifying and disabling tiered tables settings as your storage needs evolve.
Converting a heap table to a tiered table#
The pgaa.convert_to_tiered_table() function initiates the automated
offload process. If enable_replication is true , it also
converts active partitions into HTAP tables for continuous replication.
For example:
CALL pgaa.convert_to_tiered_table(
    relation := my-transactional-table::regclass,
    range_partition_column := date,
    partition_increment := 1 month,
    analytics_offload_period := 1 year,
    initial_lower_bound := 2010-01-01,
    retention_period := 5 years,
    enable_replication := true,
    minimum_advance_partitions := 2,
    maximum_advance_partitions := 5,
    drop_after_retention_period := true,
    purge_analytics_target := true
);
Where:
relation: The name of the heap table to convert to tiered table.range_partition_column: The column used for range partitioning. It must beDATEorTIMESTAMP, and it must also be included in the primary key.partition_increment: The time interval defining the size of each partition.analytics_offload_period: The threshold age at which a partition is moved from local storage to the cold tier in the data lake.initial_lower_bound: The starting value for the first partition’s lower bound.retention_period: The period after which data is purged from the cold tier.enable_replication: Iftrue, enables real-time replication to object storage for active partitions (as an HTAP table). Iffalse, the hot partitions remain as heap tables.minimum_advance_partitions: Minimum number of future partitions to maintain.maximum_advance_partitions: Maximum number of future partitions to maintain.drop_after_retention_period: Whether to drop the partition locally after the retention period expires.purge_analytics_target: Iftrue, any pre-existing tables in the object store directory or catalog entry are deleted. If set tofalseand pre-existing tables are detected, the command will fail with an error (Supported in PGD 6.3 and later).
Note
The column used for range partitioning must be a primary key.
Tables with sequences or foreign key constraints are not supported with tiered tables. You must drop the sequence or constraint before converting to a tiered table.
When used in conjunction with a catalog service, tiered tables create a
unified view in the catalog that performs a UNION of all partitions.
You can enable the bdr.prefer_analytics_engine parameter to route
queries on the entire tiered table to the PGAA engine (Seafowl or
Spark):
SET bdr.prefer_analytics_engine = TRUE;
If enable_replication is true , this setting enables DirectScan
for the entire partitioned table. Because the catalog maintains a view
of both the offloaded cold data and the replicated hot data, the
analytics engine can execute the query across the complete lifecycle of
the data.
Monitoring tiered tables#
The pgaa.list_tiered_tables() function provides a high-level
overview of all tables currently undergoing automated lifecycle
management. Its output is useful for identifying which heap tables have
been successfully converted to tiered tables, what partitioning logic is
being applied, and the current balance between between local storage and
object storage (tiered and untiered data size).
SELECT * FROM pgaa.list_tiered_tables();
Query the bdr.analytics_table view to see the low-level mapping
between your Postgres schema and the underlying analytical engine. This
table tracks the relationship between your local node group and the
remote analytics target.
SELECT * FROM bdr.analytics_table;
Use the following query to distinguish between hot and cold partitions:
SELECT
    relname AS partition_name,
    amname AS access_method
FROM pg_class c
JOIN pg_am am ON c.relam = am.oid
WHERE relname LIKE my-transactional-table%
  AND c.relkind = r
ORDER BY relname;
Modifying and disabling tiered tables#
You can modify their lifecycle policies or revert them to standard partitioned tables using a combination of PGD and PGAA commands.
Adjusting lifecycle settings
You can update the partitioning and offloading logic for an existing tiered table running the bdr.autopartition() function.
This is particularly useful if you need to shorten or extend the offload
threshold. For example, to change analytics_offload_period from 1
month to 3 months, run:
SELECT bdr.replicate_ddl_command($$
  SELECT bdr.autopartition(
    relation := public.my-transactional-table,
    partition_increment := 1 month,
    partition_initial_lowerbound := 2020-01-01,
    analytics_offload_period := 3 months
  )
$$);
See AutoPartition in PGD for details.
Warning
Modifying these settings only affects new partitions and does not reorganize existing data. If you increase the partition size, the system will not merge your current small partitions; it will only begin creating larger partitions once the current set is exhausted. While new offload timing applies to all partitions, the physical structure created under previous settings remains unchanged. !!!
Modifying replication status
If you wish to change the current setting for enable_replication ,
you must manage the replication status of the partitions.
Use the pgaa.enable_analytics_replication() or
pgaa.disable_analytics_replication() functions against the parent
table to ensure consistency across the hierarchy:
CALL pgaa.enable_analytics_replication(my-transactional-table::regclass);
Using ALTER TABLE against the parent table only sets the value of
enable_replication for future partitions; it does not retroactively
update existing child partitions. You must manually run the
ALTER TABLE command on every existing partition to ensure
consistency across your data.
Disabling tiered tables
To revert to a standard partitioned heap table:
If
enable_replicationwas active, stop replication on the parent table:
CALL pgaa.disable_analytics_replication(my-transactional-table::regclass);
Restore cold partitions. For each cold partition, run:
pgaa.restore_from_analytics(partition_name);
Or use ALTER TABLE partition_name SET ACCESS METHOD heap; .
Remove the tiered table flag from the parent table:
ALTER TABLE my-transactional-table SET (pgaa.tiered_table = false);
Stop AutoPartition (optional). To stop the table from creating new partitions entirely, run:
bdr.drop_autopartition(my-transactional-table);
Verify that the table is not listed as a tiered table anymore with
SELECT * FROM pgaa.list_tiered_tables().Verify that all partitions list
heapas their access method:
SELECT
    c.relname AS partition_name,
    a.amname AS access_method
FROM pg_class c
JOIN pg_am a ON c.relam = a.oid
WHERE c.relname LIKE my-transactional-table%
  AND c.relkind = r;