Design and architecture
Where to install Barman
One of the foundations of Barman is the ability to operate remotely from the database server, via the network.
Theoretically, you could have your Barman server located in a data centre in another part of the world, thousands of miles away from your PostgreSQL server. Realistically, you do not want your Barman server to be too far from your PostgreSQL server, so that both backup and recovery times are kept under control.
Even though there is no “one size fits all” way to setup Barman, there are a couple of recommendations that we suggest you abide by, in particular:
Install Barman on a dedicated server
Do not share the same storage with your PostgreSQL server
Integrate Barman with your monitoring infrastructure [1]
Test everything before you deploy it to production
A reasonable way to start modelling your disaster recovery architecture is to:
design a couple of possible architectures in respect to PostgreSQL and Barman, such as:
same data centre
different data centre in the same metropolitan area
different data centre
elaborate the pros and the cons of each hypothesis
evaluate the single points of failure (SPOF) of your system, with cost-benefit analysis
make your decision and implement the initial solution
Having said this, a very common setup for Barman is to be installed in the same data centre where your PostgreSQL servers are. In this case, the single point of failure is the data centre. Fortunately, the impact of such a SPOF can be alleviated thanks to two features that Barman provides to increase the number of backup tiers:
geographicalredundancy (introduced in Barman 2.6)
hookscripts
With geographical redundancy, you can rely on a Barman instance that is located in a different data centre/availability zone to synchronise the entire content of the source Barman server. There’s more: given that geo-redundancy can be configured in Barman not only at global level, but also at server level, you can create hybrid installations of Barman where some servers are directly connected to the local PostgreSQL servers, and others are backing up subsets of different Barman installations (cross-site backup). Figure :raw-latex:`\ref{georedundancy-design}` below shows two availability zones (one in Europe and one in the US), each with a primary PostgreSQL server that is backed up in a local Barman installation, and relayed on the other Barman server (defined as passive) for multi-tier backup via rsync/SSH. Further information on geo-redundancy is available in the specific section.
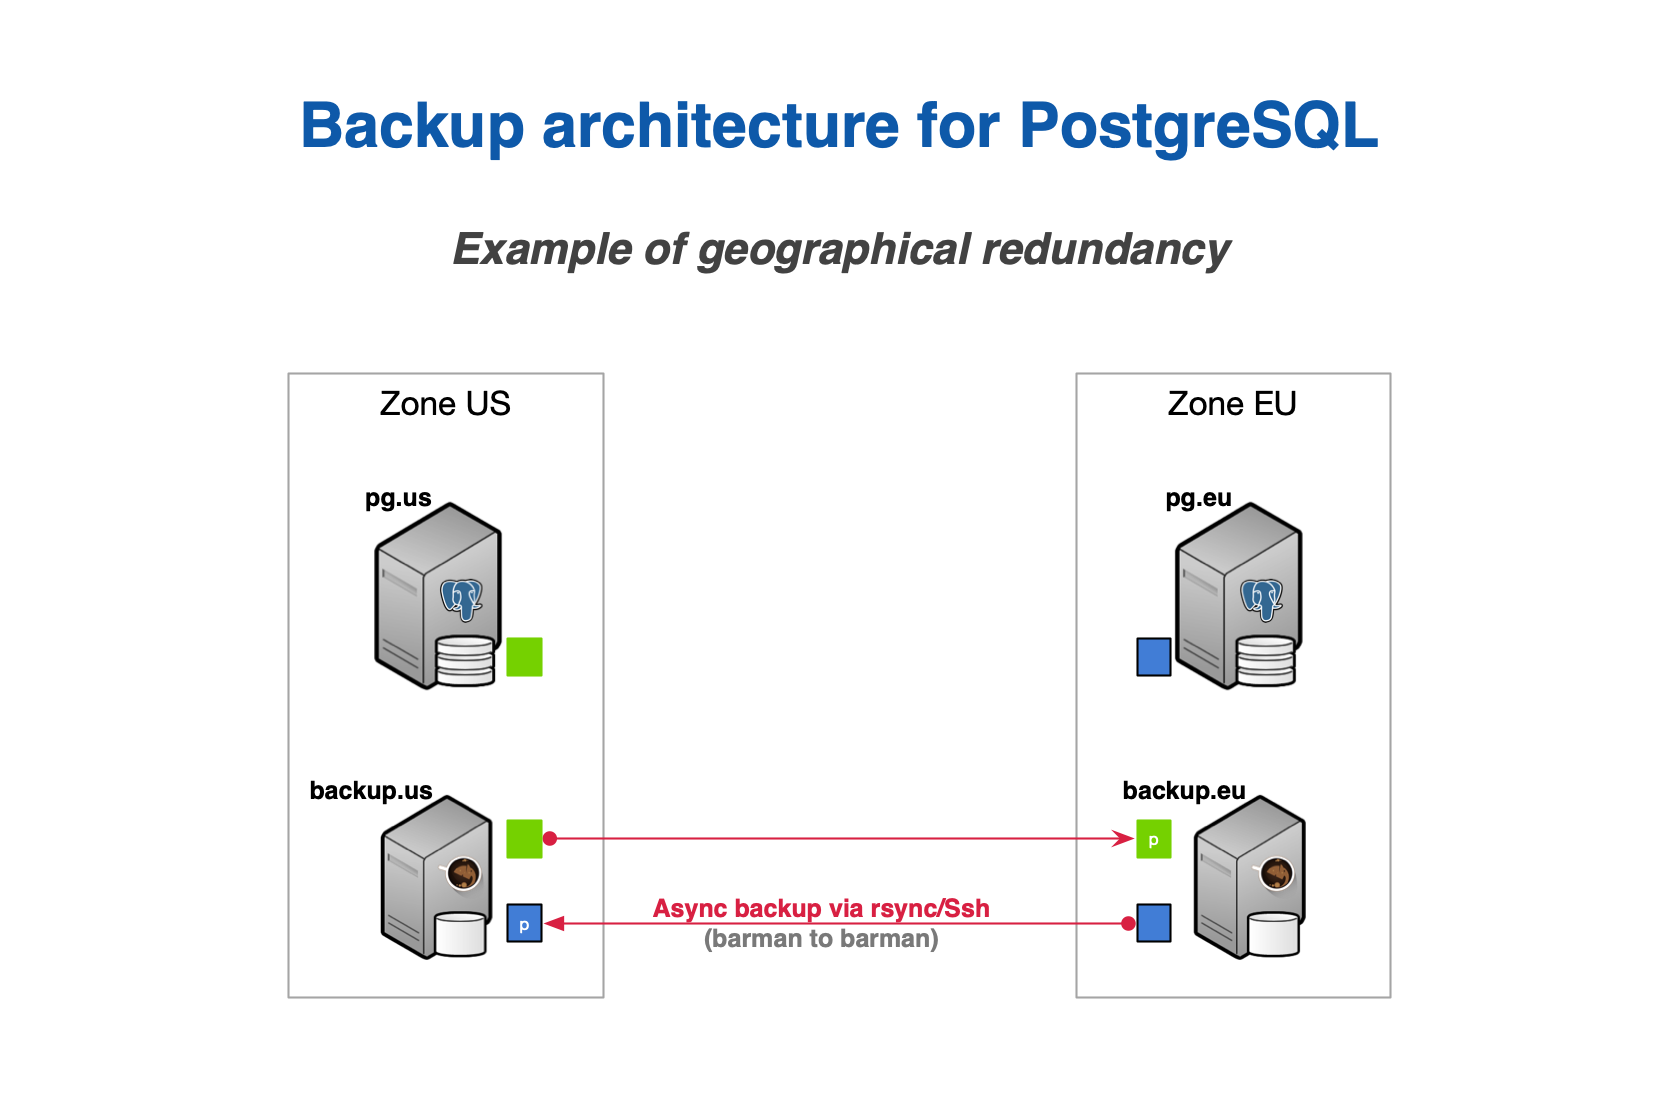
An example of architecture with geo-redundancy:raw-latex:label{georedundancy-design}
Thanks to hook scripts instead, backups of Barman can be exported on
different media, such as tape via tar , or locations, like an S3
bucket in the Amazon cloud.
Remember that no decision is forever. You can start this way and adapt over time to the solution that suits you best. However, try and keep it simple to start with.
One Barman, many PostgreSQL servers
Another relevant feature that was first introduced by Barman is support for multiple servers. Barman can store backup data coming from multiple PostgreSQL instances, even with different versions, in a centralised way. [^recver] `
^recver apply for recovery, as detailed in the section
“Requirements for recovery”.
As a result, you can model complex disaster recovery architectures, forming a “star schema”, where PostgreSQL servers rotate around a central Barman server.
Every architecture makes sense in its own way. Choose the one that resonates with you, and most importantly, the one you trust, based on real experimentation and testing.
From this point forward, for the sake of simplicity, this guide will assume a basic architecture:
one PostgreSQL instance (with host name
pg)one backup server with Barman (with host name
backup)
Streaming backup vs rsync/SSH
Traditionally, Barman has always operated remotely via SSH, taking
advantage of rsync for physical backup operations. Version 2.0
introduces native support for PostgreSQL’s streaming replication
protocol for backup operations, via pg_basebackup . [2]
Choosing one of these two methods is a decision you will need to make.
On a general basis, starting from Barman 2.0, backup over streaming replication is the recommended setup for PostgreSQL 9.4 or higher. Moreover, if you do not make use of tablespaces, backup over streaming can be used starting from PostgreSQL 9.2.
Important
Because Barman transparently makes use of pg_basebackup , features such as incremental backup, parallel backup, deduplication, and network compression are currently not available. In this case, bandwidth limitation has some restrictions - compared to the traditional method via rsync .
Traditional backup via rsync /SSH is available for all versions of
PostgreSQL starting from 8.3, and it is recommended in all cases where
pg_basebackup limitations occur (for example, a very large database
that can benefit from incremental backup and deduplication).
The reason why we recommend streaming backup is that, based on our experience, it is easier to setup than the traditional one. Also, streaming backup allows you to backup a PostgreSQL server on Windows
[3] , and makes life easier when working with Docker.
Standard archiving, WAL streaming … or both
PostgreSQL’s Point-In-Time-Recovery requires that transactional logs, also known as xlog or WAL files, are stored alongside of base backups.
Traditionally, Barman has supported standard WAL file shipping through
PostgreSQL’s archive_command (usually via rsync /SSH, now via
barman-wal-archive from the barman-cli package). With this
method, WAL files are archived only when PostgreSQL switches to a new
WAL file. To keep it simple, this normally happens every 16MB worth of
data changes.
Barman 1.6.0 introduces streaming of WAL files for PostgreSQL servers
9.2 or higher, as an additional method for transactional log archiving,
through pg_receivewal (also known as pg_receivexlog before
PostgreSQL 10). WAL streaming is able to reduce the risk of data loss,
bringing RPO down to near zero values.
Barman 2.0 introduces support for replication slots with PostgreSQL servers 9.4 or above, therefore allowing WAL streaming-only configurations. Moreover, you can now add Barman as a synchronous WAL receiver in your PostgreSQL 9.5 (or higher) cluster, and achieve zerodataloss (RPO=0).
In some cases you have no choice and you are forced to use traditional archiving. In others, you can choose whether to use both or just WAL streaming. Unless you have strong reasons not to do it, we recommend to use both channels, for maximum reliability and robustness.
Two typical scenarios for backups
In order to make life easier for you, below we summarise the two most typical scenarios for a given PostgreSQL server in Barman.
Bear in mind that this is a decision that you must make for every single server that you decide to back up with Barman. This means that you can have heterogeneous setups within the same installation.
As mentioned before, we will only worry about the PostgreSQL server
(pg ) and the Barman server (backup ). However, in real life,
your architecture will most likely contain other technologies such as
repmgr, pgBouncer, Nagios/Icinga, and so on.
Scenario 1: Backup via streaming protocol
If you are using PostgreSQL 9.4 or higher, and your database falls under a general use case scenario, you will likely end up deciding on a streaming backup installation - see figure :raw-latex:`\ref{scenario1-design}` below.
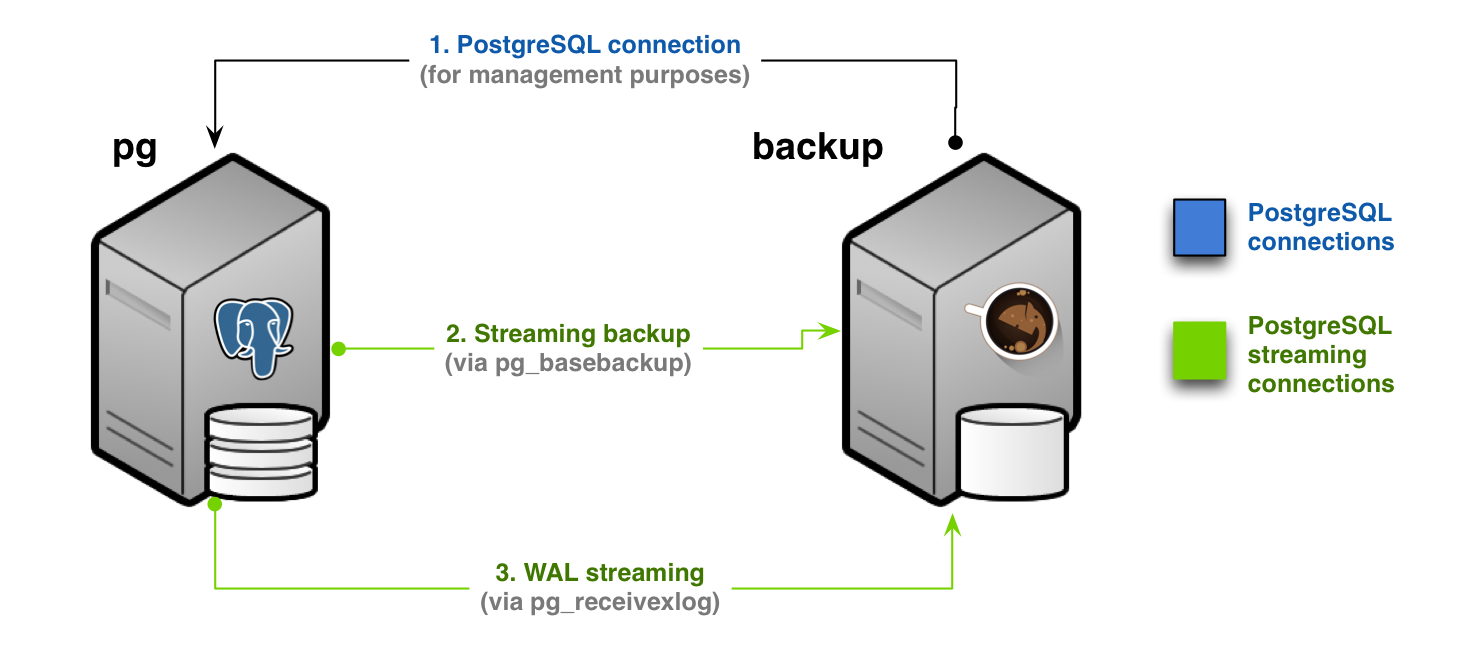
Streaming-only backup (Scenario 1):raw-latex:label{scenario1-design}
In this scenario, you will need to configure:
a standard connection to PostgreSQL, for management, coordination, and monitoring purposes
a streaming replication connection that will be used by both
pg_basebackup(for base backup operations) andpg_receivewal(for WAL streaming)
This setup, in Barman’s terminology, is known as streaming-only setup, as it does not require any SSH connection for backup and archiving operations. This is particularly suitable and extremely practical for Docker environments.
However, as mentioned before, you can configure standard archiving as well and implement a more robust architecture - see figure :raw-latex:`\ref{scenario1b-design}` below.
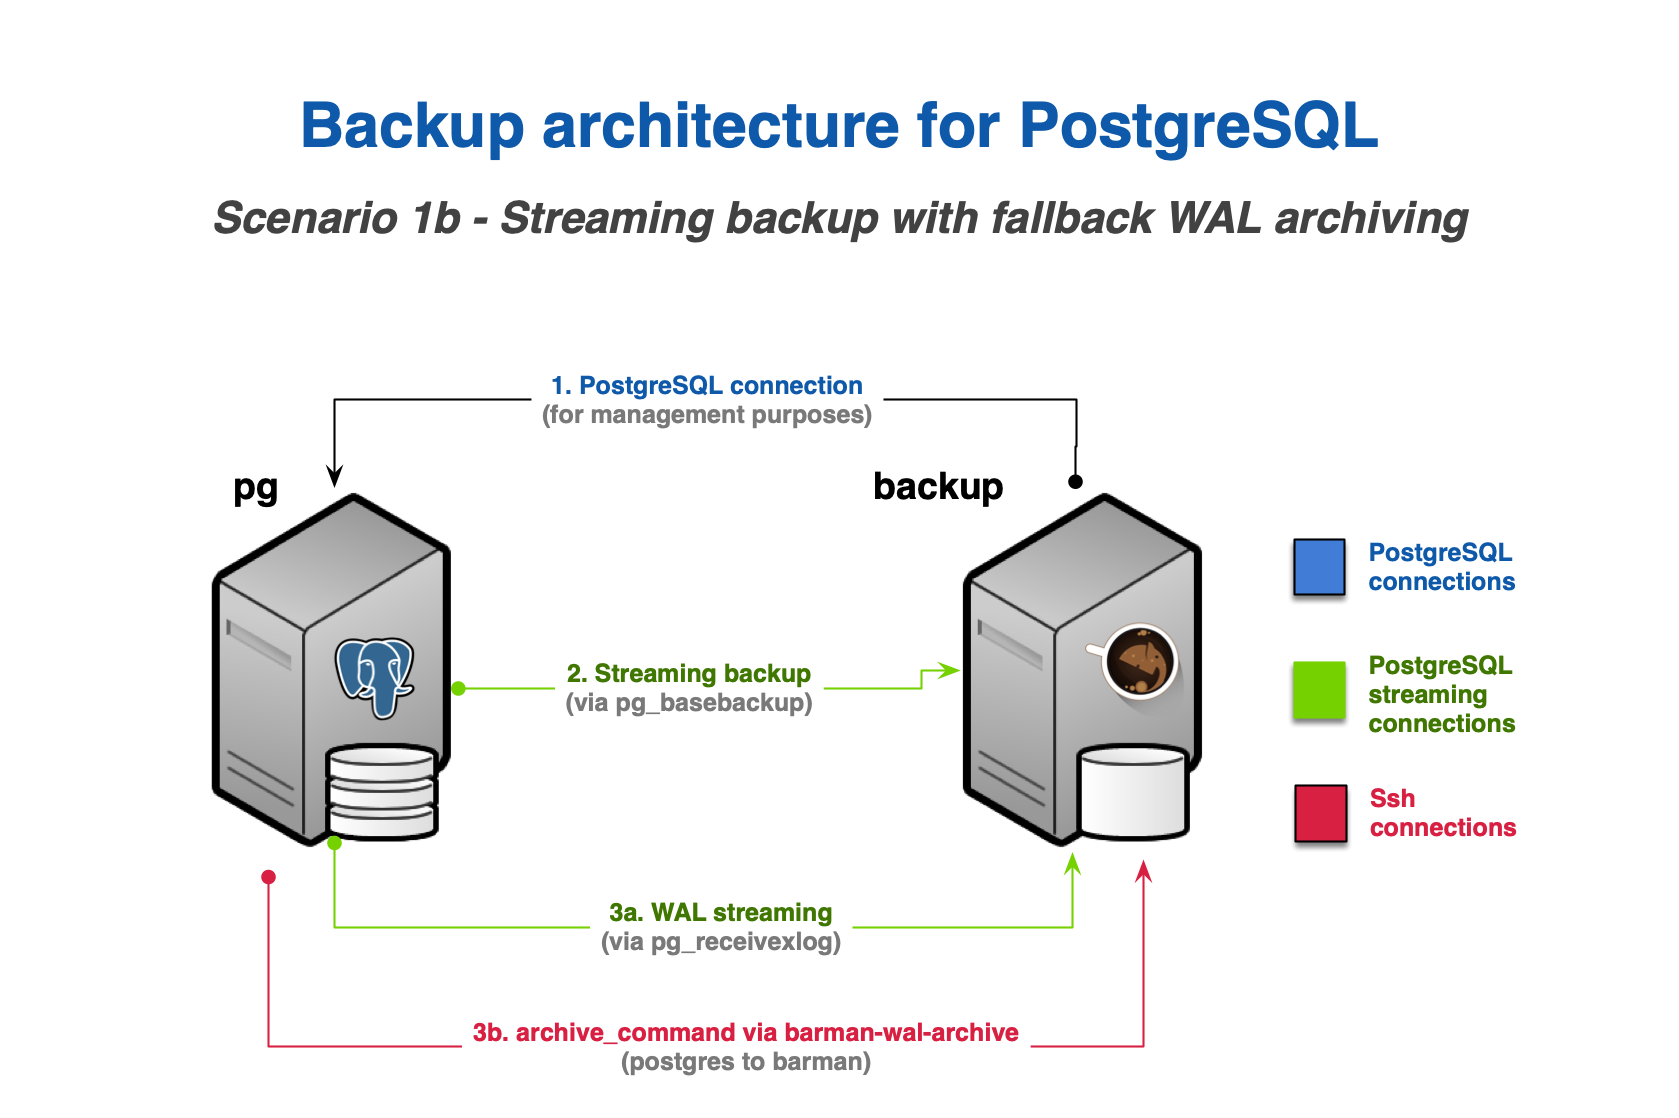
Streaming backup with WAL archiving (Scenario 1b):raw-latex:label{scenario1b-design}
This alternate approach requires:
an additional SSH connection that allows the
postgresuser on the PostgreSQL server to connect asbarmanuser on the Barman serverthe
archive_commandin PostgreSQL be configured to ship WAL files to Barman
This architecture is available also to PostgreSQL 9.2/9.3 users that do not use tablespaces.
Scenario 2: Backup via rsync /SSH
The traditional setup of rsync over SSH is the only available option
for:
PostgreSQL servers version 8.3, 8.4, 9.0 or 9.1
PostgreSQL servers version 9.2 or 9.3 that are using tablespaces
incremental backup, parallel backup and deduplication
network compression during backups
finer control of bandwidth usage, including on a tablespace basis
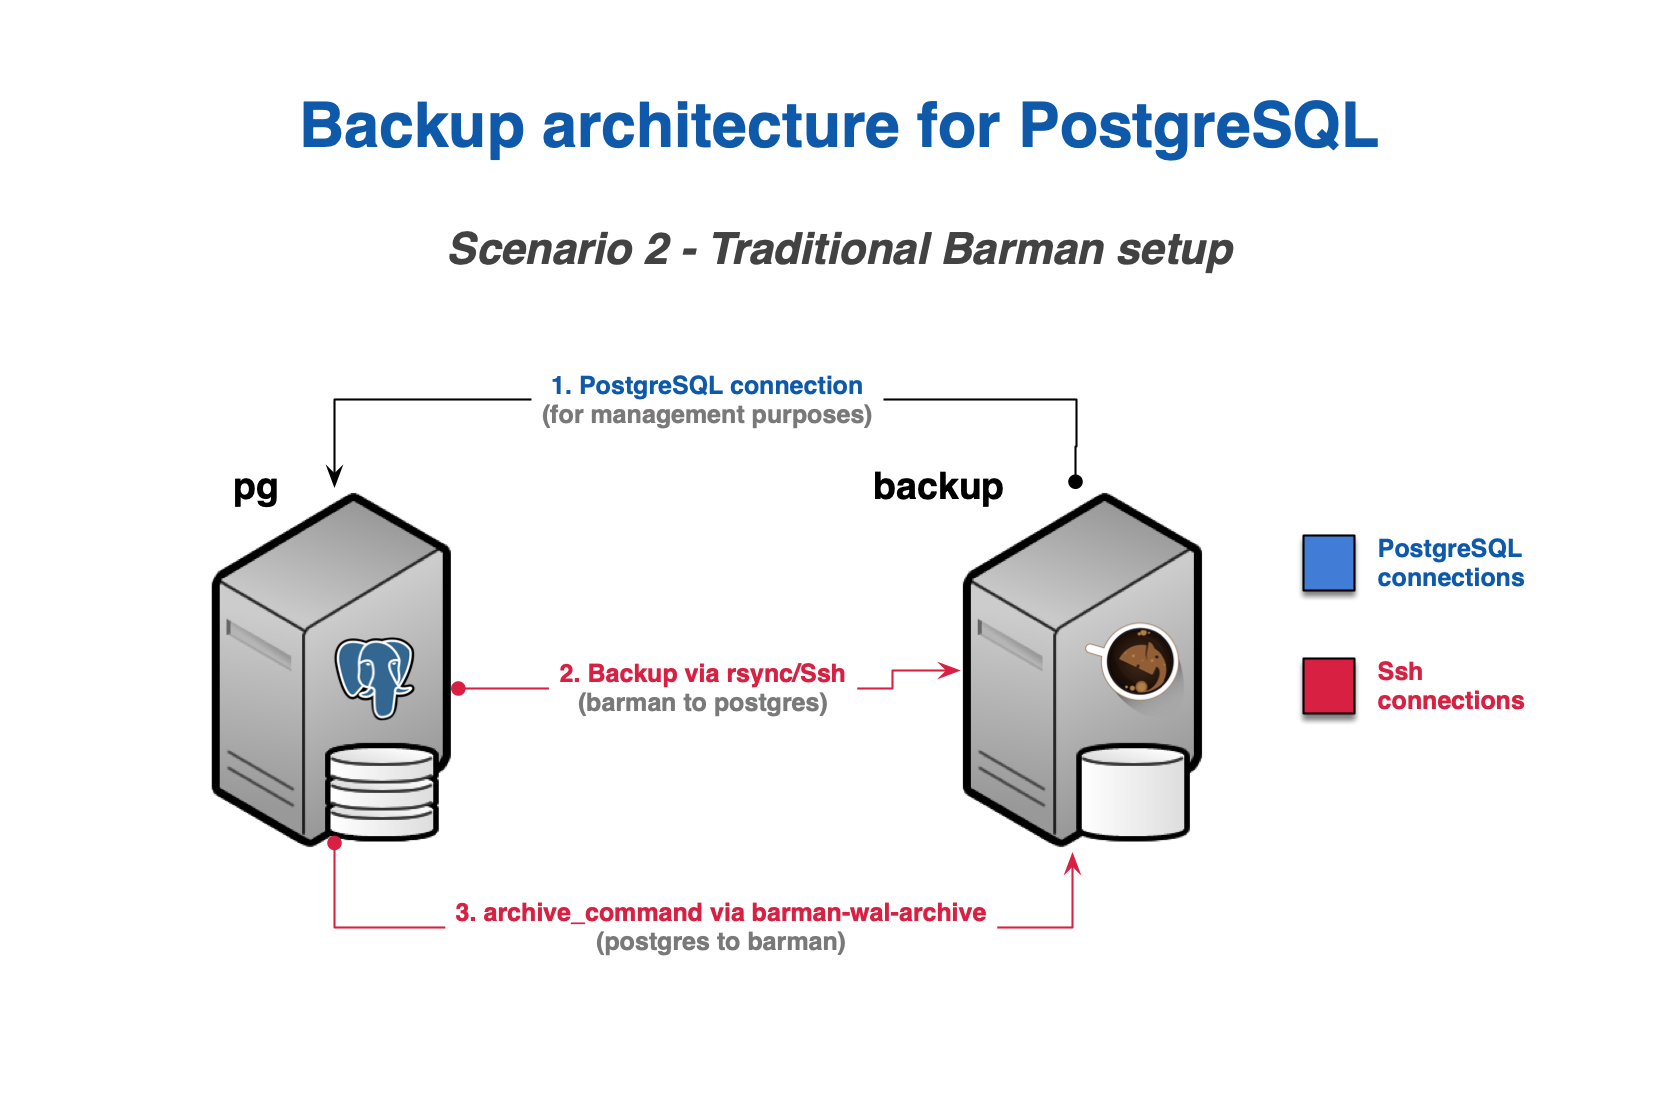
Scenario 2 - Backup via rsync/SSH
In this scenario, you will need to configure:
a standard connection to PostgreSQL for management, coordination, and monitoring purposes
an SSH connection for base backup operations to be used by
rsyncthat allows thebarmanuser on the Barman server to connect aspostgresuser on the PostgreSQL serveran SSH connection for WAL archiving to be used by the
archive_commandin PostgreSQL and that allows thepostgresuser on the PostgreSQL server to connect asbarmanuser on the Barman server
Starting from PostgreSQL 9.2, you can add a streaming replication connection that is used for WAL streaming and significantly reduce RPO. This more robust implementation is depicted in figure :raw-latex:`\ref{scenario2b-design}`.
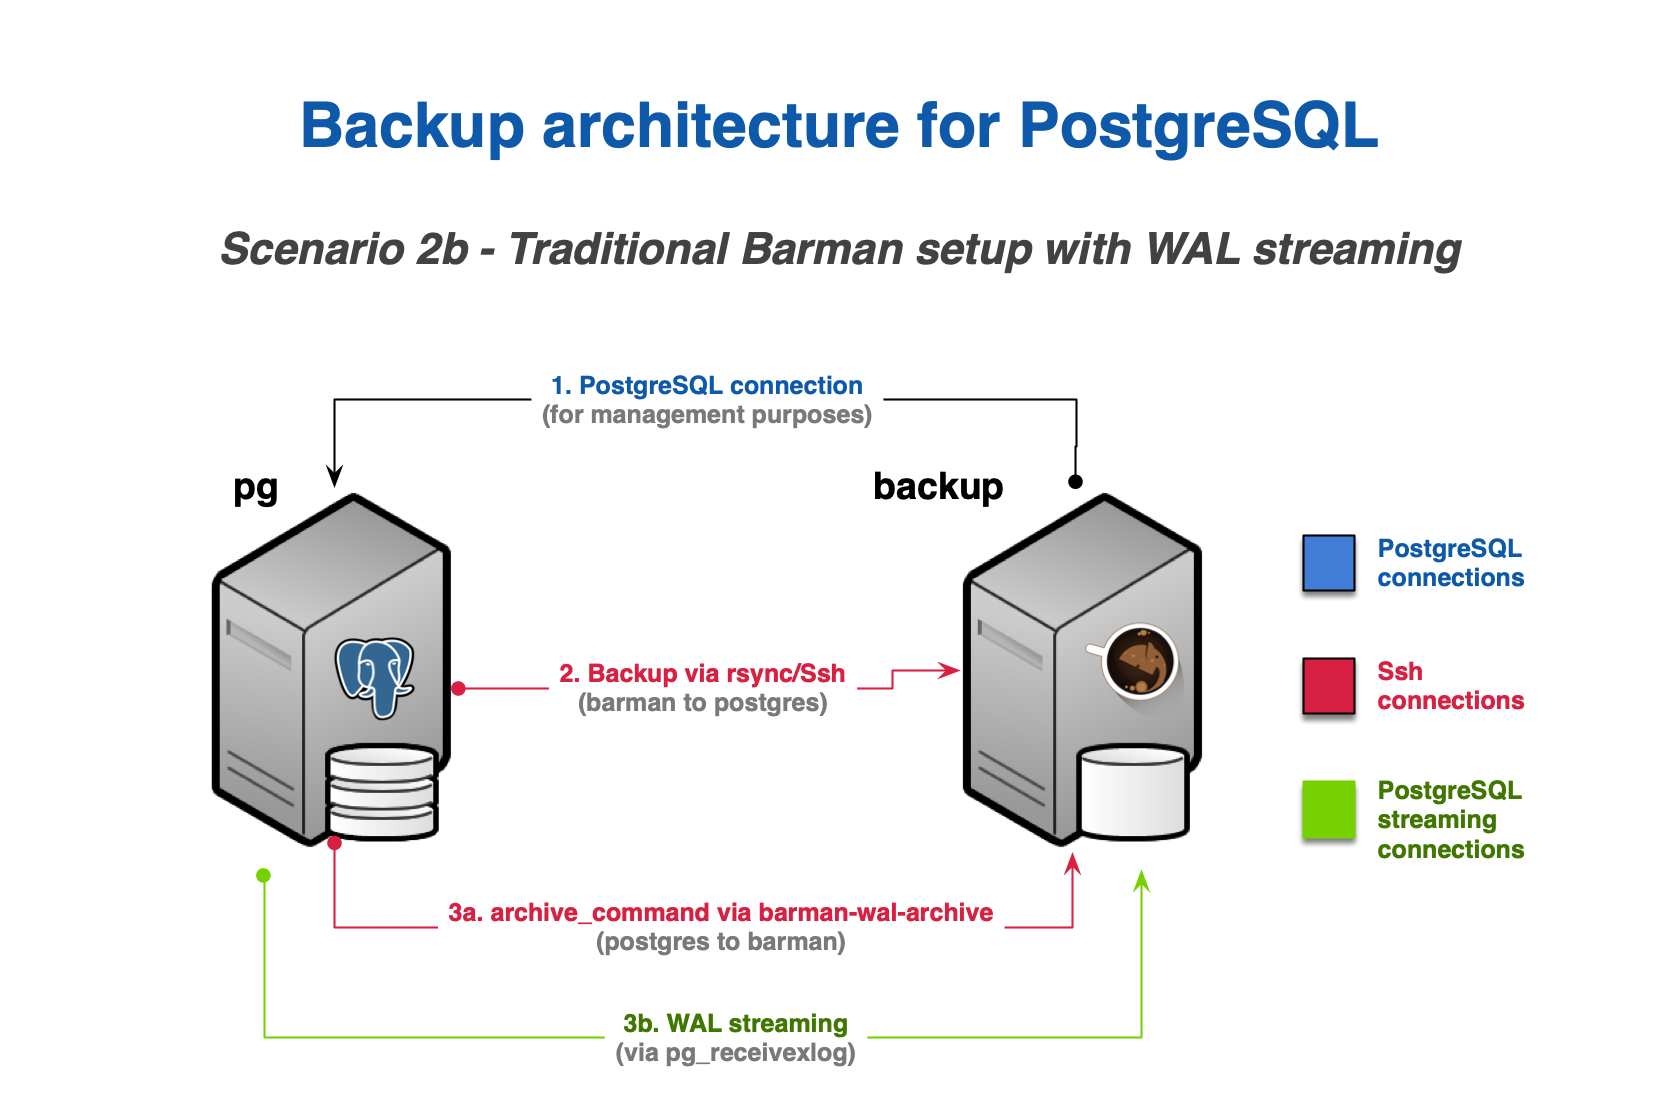
Backup via rsync/SSH with WAL streaming (Scenario 2b):raw-latex:label{scenario2b-design}