Multiple locations, data residency#
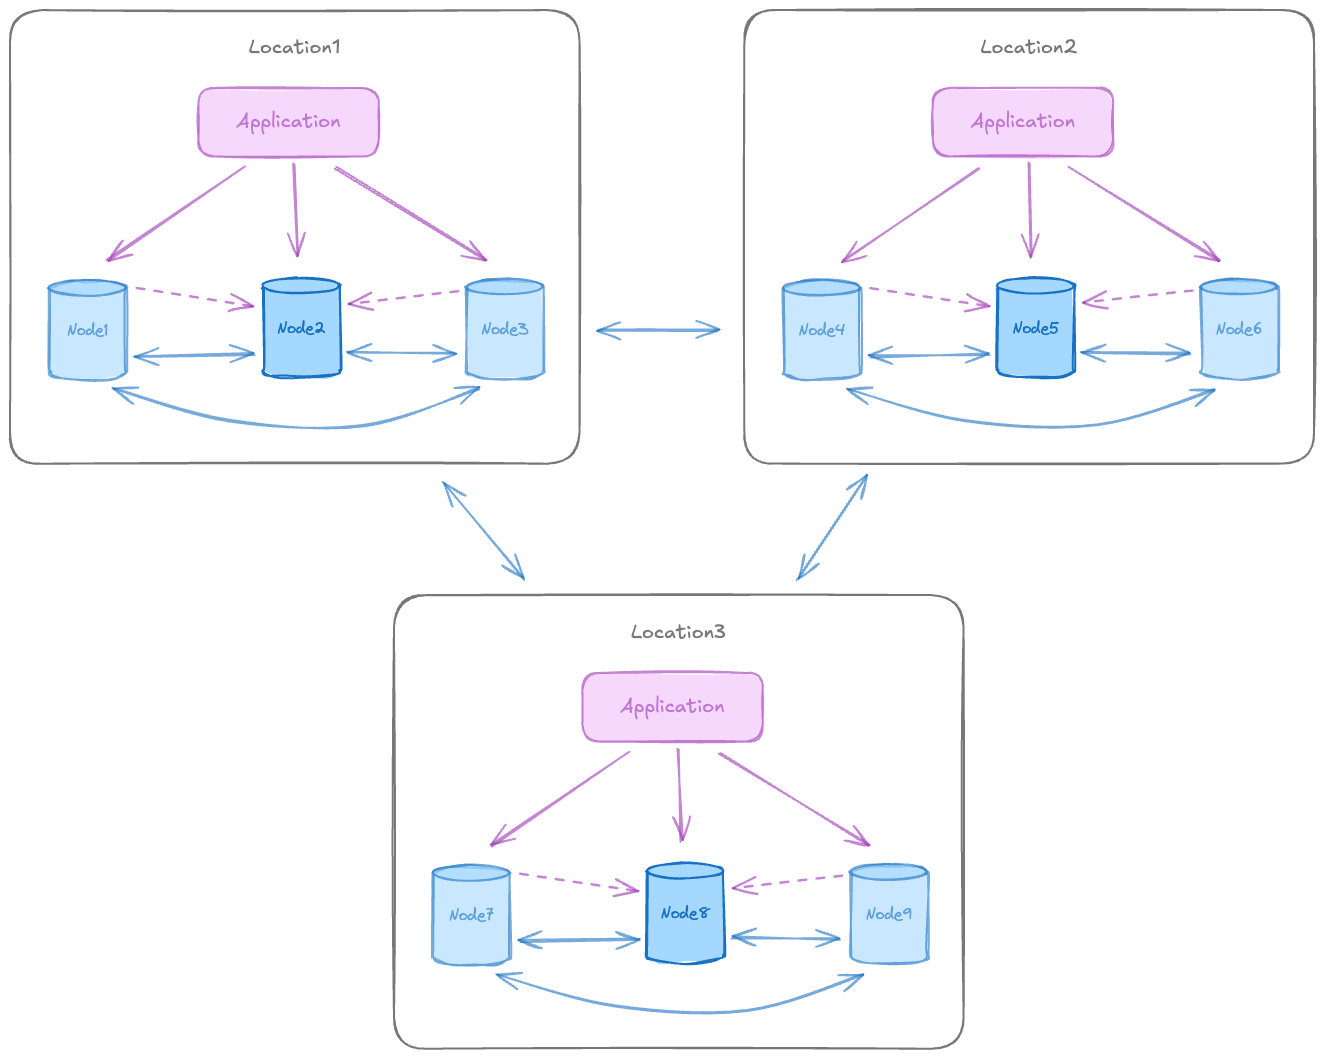
The multiple locations, data residency pattern is a multi-region deployment where personal and sensitive data stays in its origin region and is never replicated cross-border. Each region runs its own independent Raft consensus group with two or more data nodes for local high availability (HA).
Only global reference data, including product catalogs, configuration, and anonymized analytics, replicates between regions, enabling compliance with GDPR, CCPA, and other data localization laws.
Multiple locations, data residency topology#
Selective replication works by classifying data into two categories.
Local-only (replicated only within the region): personally identifiable information (PII), customer data, financial records, and healthcare data.
Global (replicated everywhere): product catalog, configuration, reference data, and anonymized analytics.
Diagram legend#
Symbols represent node types, group containers, and connection types.
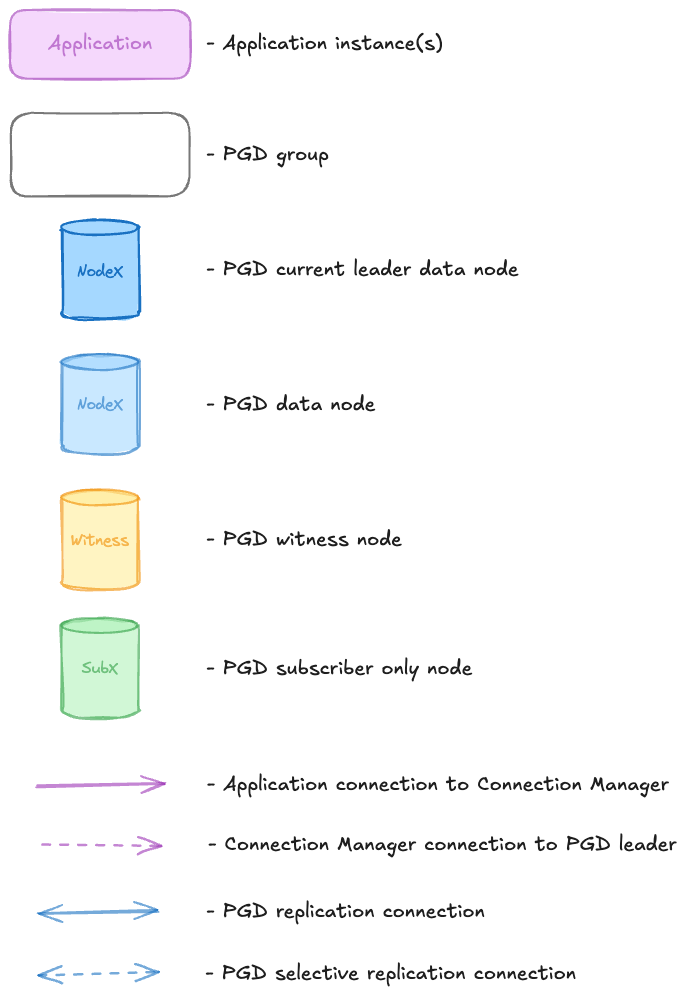
Diagram legend showing node types, group containers, and connection types#
When to use this pattern#
This pattern suits global enterprises that need geo-replication with strict regulatory requirements for data localization, including financial services where banking data must stay in-country, healthcare where patient data residency is required, government institutions, and multinational SaaS where customer data must stay in specific jurisdictions.
The advantages of this pattern include the following:
Allows compliance with GDPR, CCPA, and data localization regulations.
Avoids cross-border data transfer legal complexity.
Provides low latency for regional users by keeping data in-region.
Single global application codebase with regional data routing.
Isolates regional failures so one region going down doesn’t affect others.
There are some limitations to keep in mind:
No cross-region view of all data.
Schema design must separate local and global data clearly.
Monitoring must track per-region compliance.
Recommended commit scopes for this pattern#
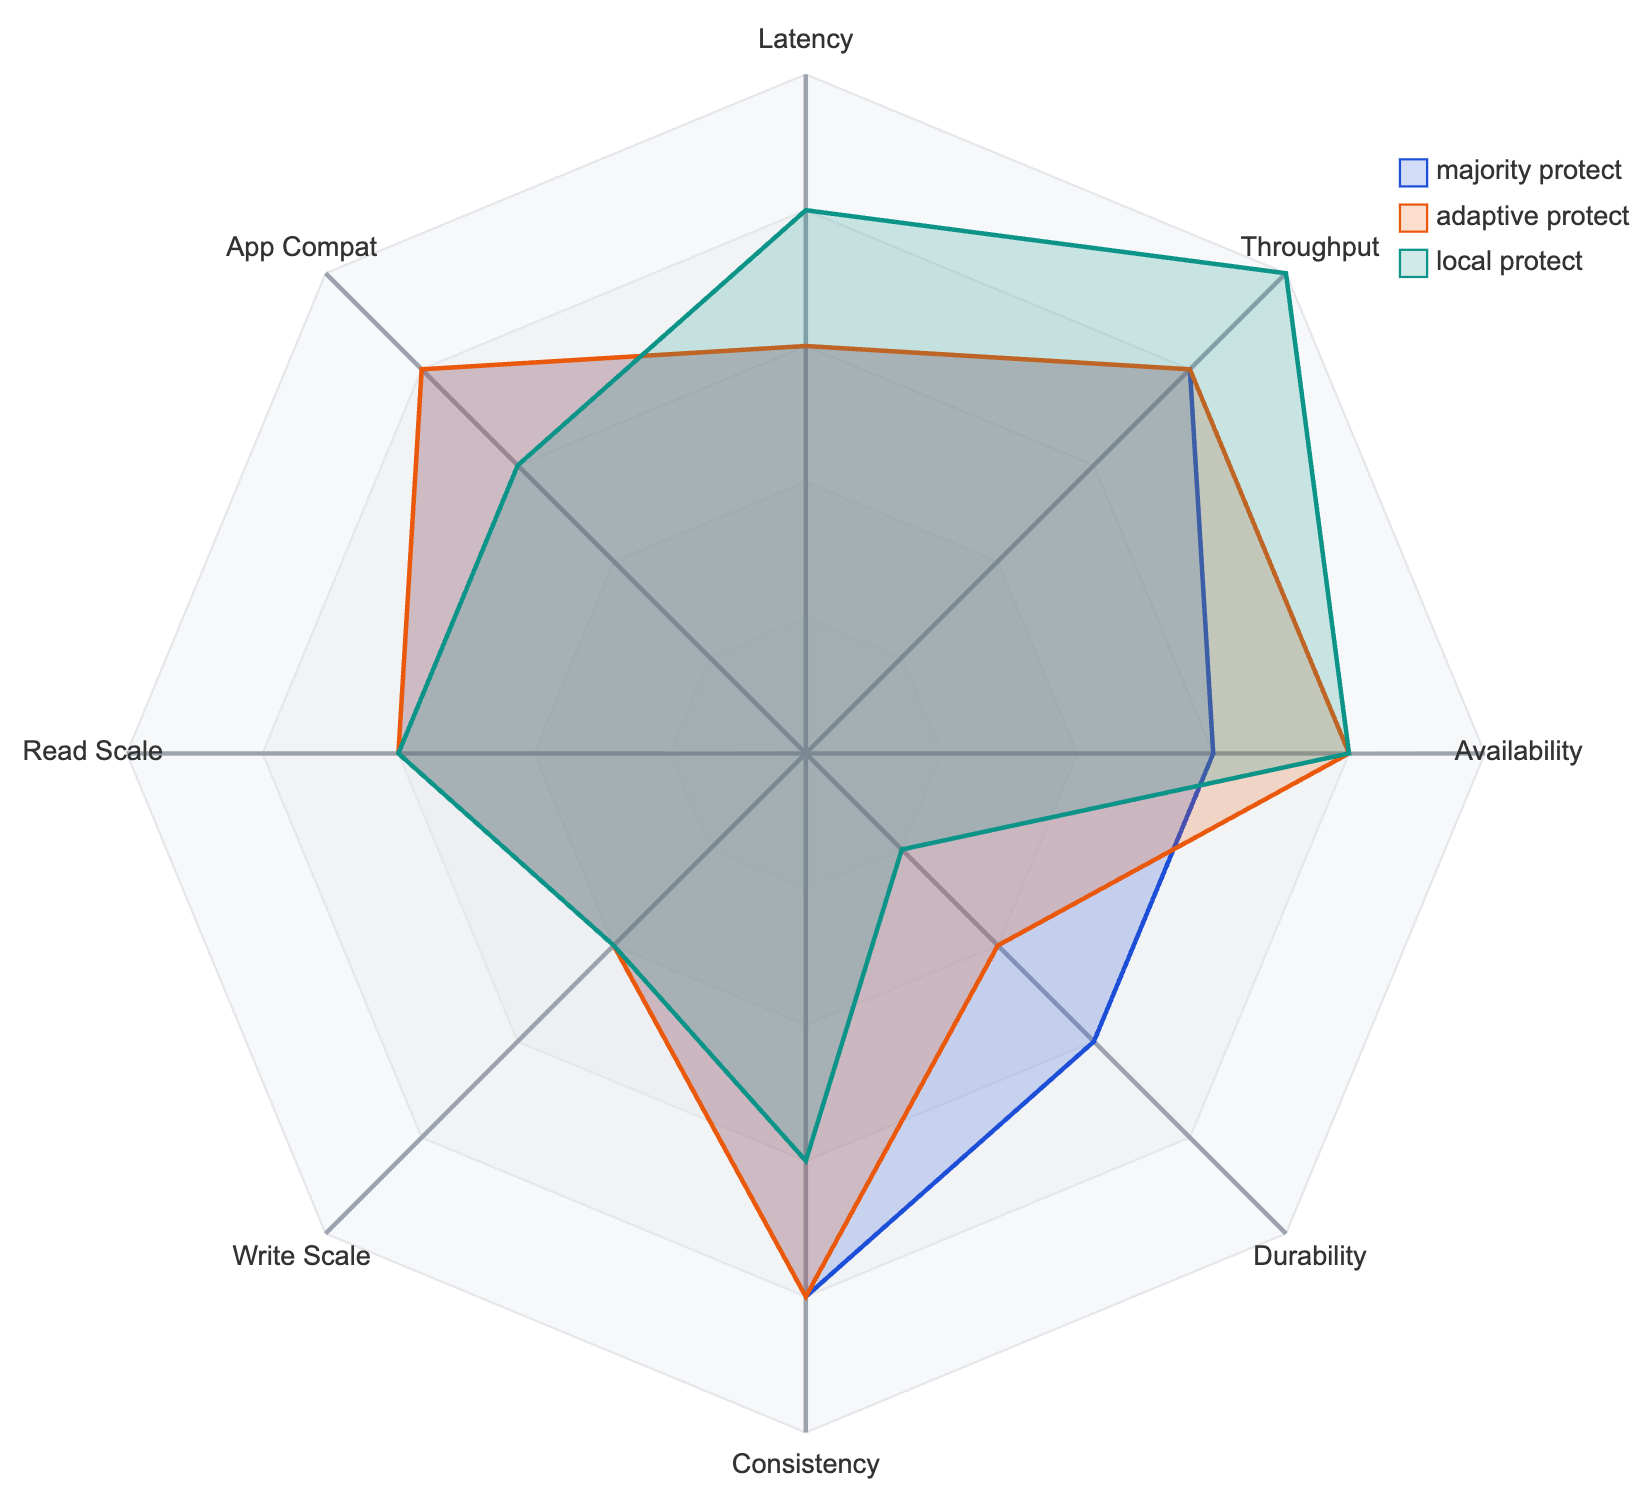
Majority protect: synchronous replication to the majority of the nodes in a region. The most commonly recommended scope for production use.
Adaptive protect: synchronous replication to the majority of nodes when available, degrading automatically to asynchronous replication after a configurable timeout. Recommended when using two data nodes and one witness.
Local protect: asynchronous replication with durability only for the local node. Not recommended for production use.
Commit scopes make different trade-offs across performance, durability, consistency, and scalability.
Multiple locations, data residency behavior diagram#