Single data group#
The single data group is the foundational PGD deployment pattern, providing high availability within a single location. Three data nodes form a Raft consensus group, with Connection Manager handling write leader routing automatically.
Nodes can be spread across multiple availability zones for added resiliency, though doing so increases write latency when using majority or all protect commit scopes.
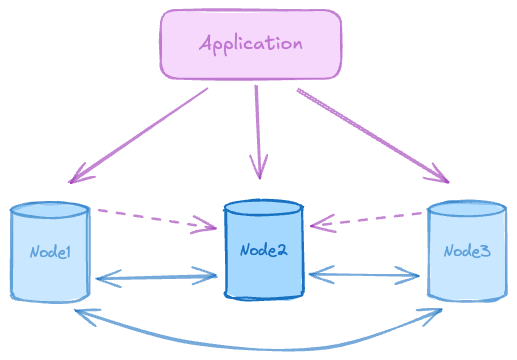
Single data group topology#
Diagram legend#
Symbols represent node types, group containers, and connection types.
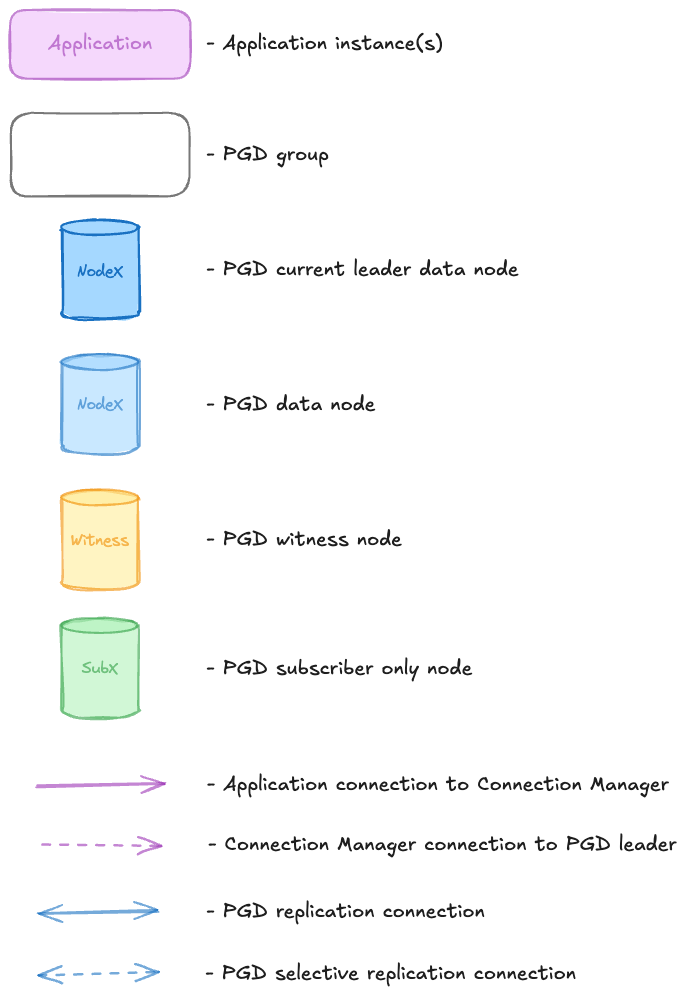
Diagram legend showing node types, group containers, and connection types#
When to use this pattern#
The single data group is the standard high availability (HA) deployment within a single data center. It tolerates single node failure and provides automatic failover in seconds, making it well suited to applications that need HA within a single region and can’t afford extended downtime during major version upgrades or blocking maintenance tasks.
The advantages of this pattern include the following:
Simplest topology to deploy, operate, and troubleshoot.
Raft majority always available, surviving one node failure.
Lowest write latency when deployed in a single data center (DC).
Survives single AZ failure when deployed across multiple availability zones.
Automatic failover in seconds with no operator intervention.
Low cost at three nodes minimum.
There are some limitations to keep in mind:
No disaster recovery. A DC-level failure takes down the entire cluster.
When deployed in a single DC, all nodes share the same failure domain.
Not suitable for regulatory requirements mandating geographic separation.
When used with two data nodes and a witness, durability options are limited.
Recommended commit scopes for this pattern#
Majority protect: synchronous replication to the majority of the nodes. The most commonly recommended scope for production use.
Quorum Commit: coordinates the commit decision across all participating nodes before any node commits locally. Recommended for workloads requiring strict distributed consistency, such as payments and core banking. Witness nodes don’t contribute to quorum, so all three nodes must be data nodes. Use
MAJORITY ORIGIN GROUP QUORUM COMMIT ABORT ON (timeout = 6s).Adaptive protect: synchronous replication to the majority of nodes when available, degrading automatically to asynchronous replication after a configurable timeout. Recommended when using two data nodes and one witness.
All protect: synchronous replication to all nodes in the group. Provides the highest durability guarantee, but increases write latency and reduces availability tolerance when any node fails.
Local protect: asynchronous replication with durability only for the local node. Not recommended for production use.
Commit scopes make different trade-offs across performance, durability, consistency, and scalability.
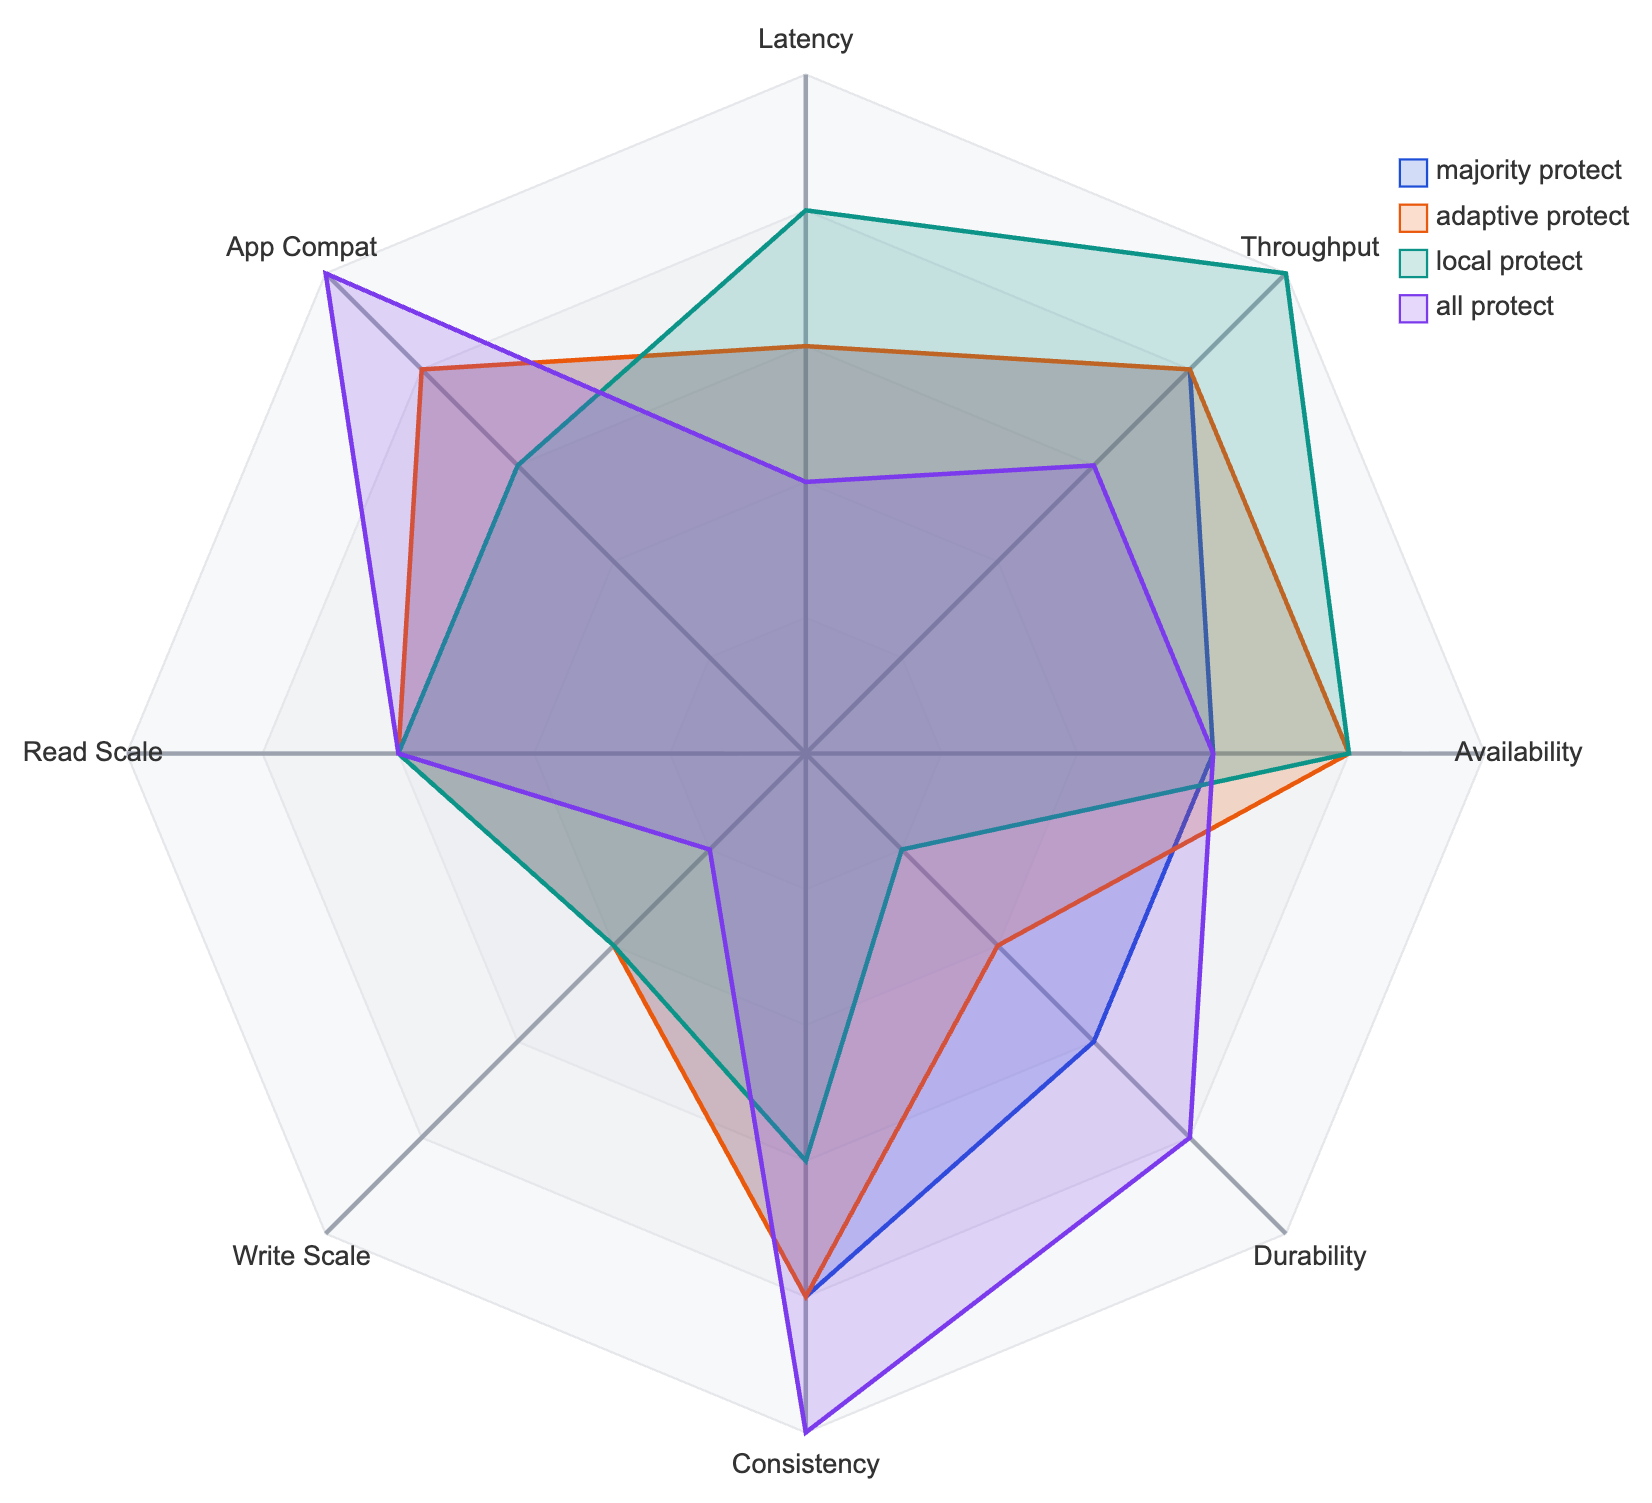
Single data group behavior diagram#